Project visuals
Interface screenshots, reconstructed deliverable extracts and workflow illustrations are labelled. All visuals use fictional content and metadata, with client branding removed. Select an image to view it full size.
The engagement
An international pharmaceutical group ran a Bynder DAM holding thousands of assets whose mandatory fields, legal and organizational, were filled in, while the descriptive fields were largely empty: target audience, marketing themes and topics, content type. The brief had three parts: index automatically from everything the platform holds (metadata, file name, visual content), never send the whole library to a model, and run the tool on the client's own API keys while reporting what it spends.
We treated "do not prompt the whole library" as an architectural constraint, not a usage guideline. An agent only runs on a batch built in advance, and five gates remove, before the first call, every asset with nothing to gain from it: explicit targeting, eligibility (target field still empty, supported format), exclusion of what was already analysed with the same instructions and the same model, volume and budget caps that block rather than warn, then a reviewed sample before any full run. The estimated cost is shown before launch. Only the lists relevant to the task go into the prompt: about 4,300 tokens instead of 84,000 for the full taxonomy, most of whose options, inherited from an earlier migration, had no indexing value.
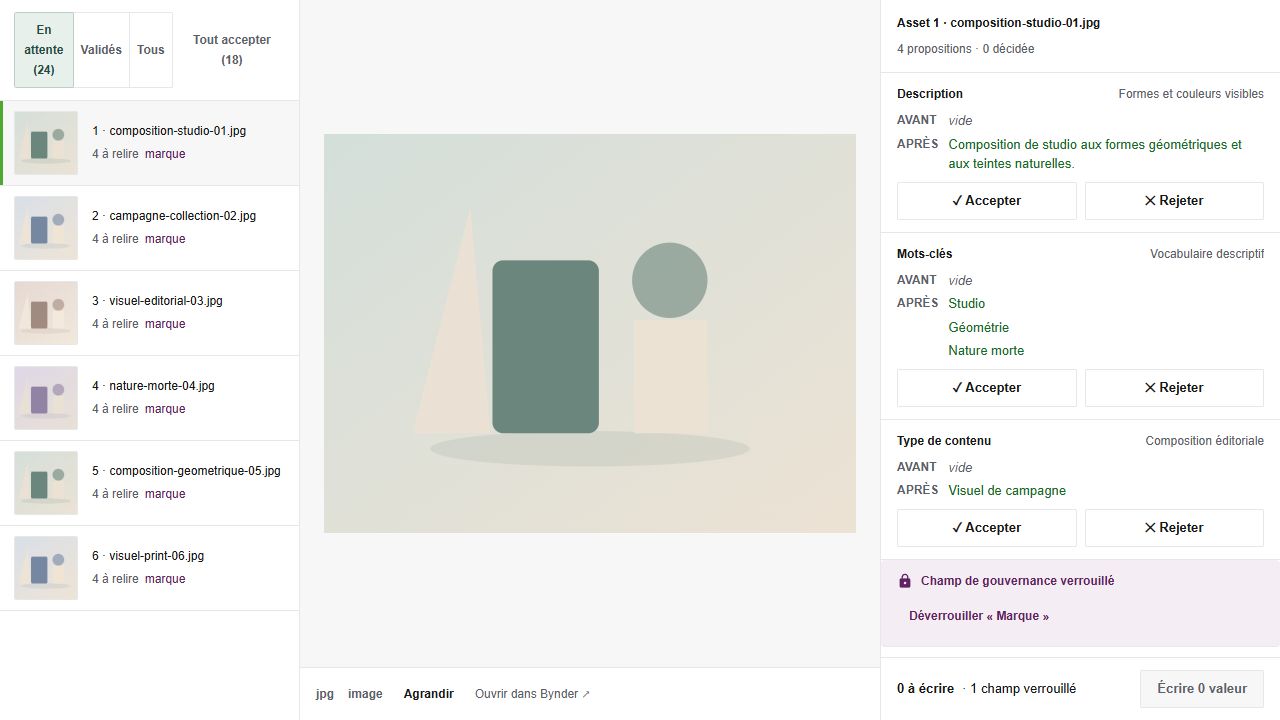
The agent proposes; it does not write. Every proposal carries a justification, and any value missing from the metaproperty's vocabulary is rejected by a server-side re-check: the output schema guarantees the shape of the answer, never its content, and in the very first trials a model slipped one field's option into another. Legal and organizational fields arrive locked, writing them requires a second confirmation in which the user retypes the number of affected assets, and every applied batch stays logged and reversible. The instructions sent to the model are visible and editable on screen, and their version is part of the key that decides whether an asset has already been analysed.
We delivered the specification, the technical architecture documents and a working prototype on the DAM's real data, playable end to end and able to run on a locally served model, with no image ever leaving the machine. The first quality benchmark was itself audited before being trusted: the client's naming convention already contained part of the answers, so the accuracy it reported did not measure what the model actually saw. Rather than publish that figure, we reworked the protocol before settling on one: a frozen, deduplicated sample, a blind pass without the file name, and sample sizes published field by field.
Takeaway
A takeaway for your project
We made an indexing workflow testable in which AI proposes and the user approves, with scope and cost reviewed before each run.
Technologies
- Bynder
- React
- TypeScript
- Node.js
- Ollama
- Python
Your next step
Want to test AI against your indexing needs?
Share the fields to complete, relevant formats and approval rules you need. We can scope a prototype and its evaluation protocol before considering operational use.
Discuss your project